23 ml KNN estimate
Keywords
Summary
228 words
Critical Evaluation
Value of the Information & Strength of the Argument
The lecture provides substantial value by clearly distinguishing between two non-parametric density estimation techniques: Parzen windows and k-NN estimation. It systematically builds the argument that k-NN estimation fixes the number of neighbors k and adapts the volume, whereas Parzen windows fix the volume and count samples. The worked examples are particularly instructive, walking through the step-by-step window expansion and density calculation, which solidifies understanding. The transition to the k-NN rule is well-motivated: the instructor argues that directly estimating the posterior probability via majority voting is simpler and more practical than estimating likelihoods and applying Bayes rule. The derivation showing that the posterior equals k_i/k is elegant and reinforces the method’s intuitive appeal. The discussion of practical issues, such as the need for odd k to avoid ties and the problem of unbounded window growth for small n, adds depth. However, the argumentation could be strengthened by discussing limitations of k-NN (e.g., curse of dimensionality, choice of k) and by comparing with other classifiers. Overall, the reasoning is sound and pedagogically effective, though it remains at an introductory level.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is generally high for a lecture: the mathematical formulas are correct, the derivations are logical, and the examples are consistent. The instructor uses precise terminology and clearly separates the k-NN estimation from the k-NN rule, warning students not to confuse them. However, no external sources, references, or citations are provided, either in the description or during the lecture. The material aligns with standard textbooks (e.g., Duda & Hart, Bishop), but this is not acknowledged. The title ‘23 ml KNN estimate’ is an abbreviated label that accurately reflects the content, though it is not descriptive and lacks context. The lecture does not include any advertising segment. The absence of source attribution is a notable weakness in terms of scholarly rigor, but the content itself is reliable and well-presented.
323 words
Title / Content Match
The title '23 ml KNN estimate' is a terse, abbreviated label that accurately reflects the lecture's focus on k-nearest-neighbor density estimation, though it is not descriptive and omits the broader context of non-parametric methods.
Quality & Reliability
7/10
The lecture presents standard, well-established material on non-parametric density estimation (Parzen windows, k-NN estimation, k-NN rule) consistent with classic pattern recognition textbooks. The mathematical derivations are correct and the worked examples are coherent. However, no external sources, references, or citations are provided in the description or during the lecture, and the presentation relies entirely on the instructor's exposition. The absence of any bibliography or links slightly reduces the score.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction: recap of Parzen window and introduction to k-NN estimation as a growing window method.
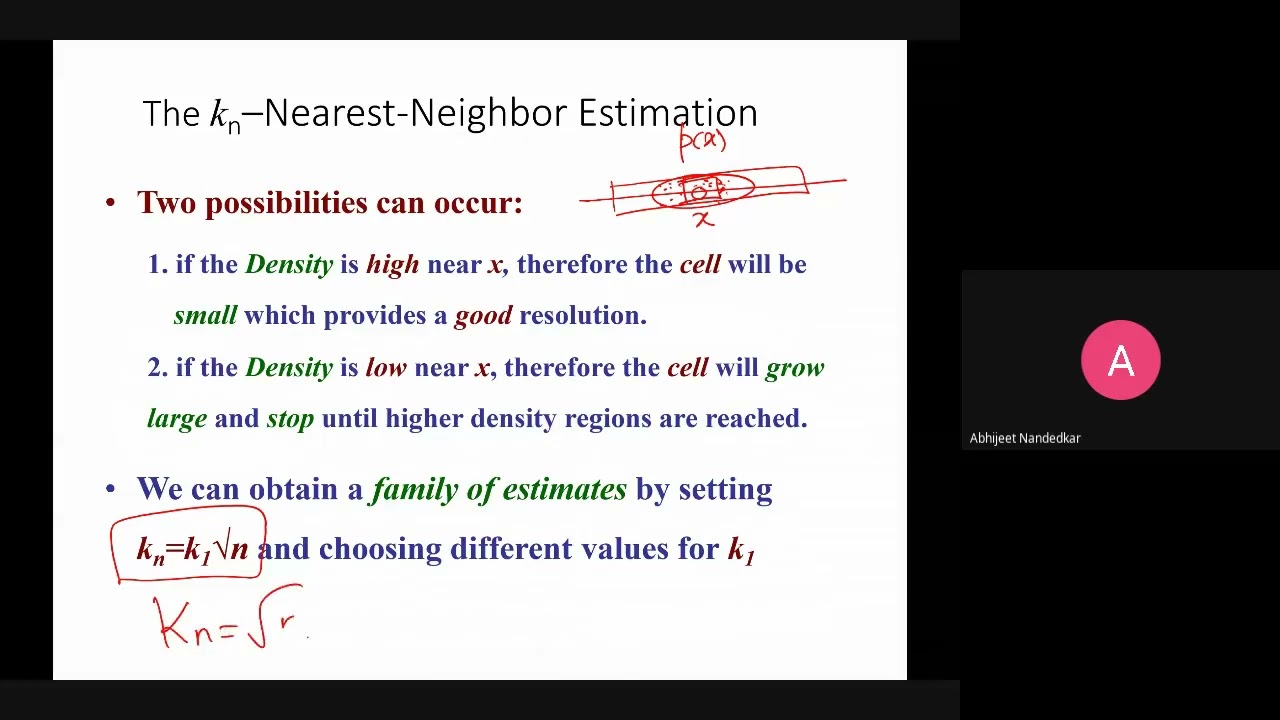
- Explanation of k-NN procedure: fix k (e.g., sqrt(n)), expand cell until k samples are captured.
- Comparison of Parzen window (fixed volume) vs. k-NN estimation (fixed k, variable volume).
- Discussion of density estimation quality: high density yields better estimates; low density requires larger windows.
- Problem with n=1: unbounded window growth leads to non-integrable density estimate.
- Worked example: 1D data, k=6, x=3.1, iterative window expansion to find 6 neighbors, density estimate 0.3.
- Classification example with two classes: compute likelihoods and posteriors using k-NN estimation and Bayes rule.
- Introduction to k-NN rule: direct posterior estimation via majority voting among k nearest neighbors.
- Derivation: posterior P(Omega_i|x) = k_i/k, with example of multiple classes.
- Practical advice: choose odd k to avoid ties; summary and preview of next lecture.
Contribution & Novelties
The lecture does not present original research; it is a pedagogical exposition of established non-parametric methods. Its novelty lies in the clear, step-by-step comparison between Parzen windows and k-NN estimation, and the smooth transition to the k-NN rule. The worked examples are detailed and help bridge theory and practice. For learners, the main contribution is the structured explanation of how to implement k-NN estimation and rule, including the iterative window expansion and the derivation of the posterior probability.
Pour aller plus loin :
- k-nearest neighbors algorithm — Wikipedia article covering the k-NN rule, its properties, and applications.
- Parzen window — Wikipedia article on Parzen window density estimation, the method contrasted in the lecture.
- Non-parametric statistics — Overview of non-parametric methods, providing broader context.
- Pattern Classification by Duda, Hart, and Stork — Classic textbook covering Parzen windows and k-NN in detail (no URL provided to avoid inaccuracy).
146 words
Radar Profile
The radar profile shows high scores in information quantity and quality, reflecting the lecture's thorough coverage and clear explanations. Technical level is moderate, suitable for students with some background. Reliability is good but not perfect due to lack of citations. Overall, a solid educational resource.