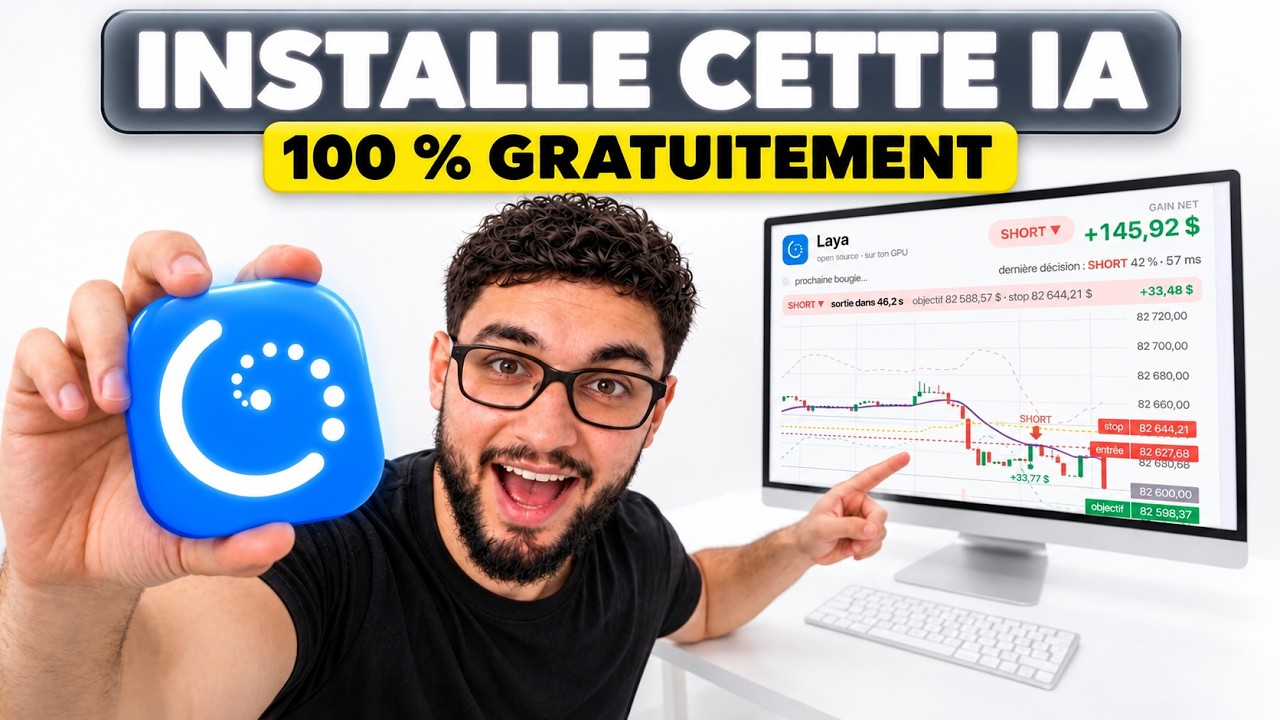
J'ai installé une IA qui décide TOUT pour moi, (GRATUIT)
I installed an AI that decides EVERYTHING for me (FREE)
Keywords
Summary
173 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides concrete, quantitative data from real-time tests, which adds practical value for those considering these AI models for automation. The creator transparently admits limitations, such as the poor trading strategy, and distinguishes between model speed/efficiency and strategy quality. However, the argumentation relies heavily on personal experiment design without controlling variables or providing statistical significance. The claim that Jev is 90x cheaper is derived from his specific tests, which is useful but not broadly generalizable. The demonstration of the open-source alternative Laya is valuable, and the tutorial aspect enhances the practical utility.
Scientific Rigor, Source Quality, Title Accuracy
The video is scientifically weak: no external sources are cited, and the methodology is anecdotal. The creator mentions TypeSafe and its founders but does not link to any papers or official benchmarks. The performance numbers are presented as direct from his tests, but there is no code or reproducible protocol shown. The title accurately reflects the content, though ‘decides everything’ is hyperbolic. The description provides a link to a free pack for running the tests, but not to the actual models’ documentation. The absence of peer review or independent validation limits the reliability of the claims. No comments were provided for analysis.
210 words
Title / Content Match
The title accurately reflects the content: the creator installs an AI decision model and tests it in various scenarios. Minor exaggeration in 'decides EVERYTHING' but acceptable.
Quality & Reliability
6/10
The video presents hands-on tests comparing Jev and Claude, but relies on the creator's own measurements without external peer review. Some claims are plausible but not independently verified.
Chapters
- Dans cette vidéo
- Jev, l'IA qui décide à ta place
- L'histoire de TypeSafe
- Comment Jev répond (oui, non, probabilité)
- Jev contre Claude : précision, vitesse, prix
- Le programme des tests
- Place aux tests en direct
- Épreuve 1 : scalping sur le bitcoin
- Épreuve 2 : Tetris piloté par l'IA
- Épreuve 3 : 100 prospects en 18 secondes
- Le motion design pour le prospect
- Épreuve 4 : le tri de 100 avis clients
- Le tutoriel gratuit dans la description
- Laya, l'alternative gratuite en local
- Jev, Laya et Opus : leads et trading
- Conclusion
Cited Sources
- Free pack (n8n form) — The creator offers a free pack with tutorials and scripts for reproducing the tests.
- Creative Commons Attribution 4.0 — Music credits license used in the video.
Contribution & Novelties
The video offers an early practical evaluation of Jev, a newly released decision-making AI, and demonstrates its efficiency in high-frequency tasks like trading and data scraping. It also introduces a free open-source alternative (Laya) and provides tutorials for local installation. The novelty lies in the real-time comparative tests and the emphasis on cost-effectiveness for bulk decision-making applications.
Pour aller plus loin :
- Automated trading — Relevant to the scalping test and automated decision-making in financial markets.
- Large language model — Provides background on the technology behind Claude and similar models.
- Open-source software — Context for Laya and the local deployment aspect.
- Decision making — Theoretical framework for the decision-focused nature of Jev.
112 words
Radar Profile
The radar profile shows high scores for quantity of information and technical level, but lower on quality and reliability, reflecting the detailed but informal nature of the tests. The overall balance suggests a moderately useful but not fully rigorous contribution.