Liad Erez - The Sample Complexity of Multiclass and Sparse Contextual Bandits
Keywords
Summary
154 words
Critical Evaluation
Value of the Information & Strength of the Argument
The talk provides significant value by presenting tight sample complexity bounds for two key settings in learning theory. The first result improves on prior work and achieves the information-theoretic optimum, and the second solves an open problem by characterizing the exact dependence on both the Natarajan and DS dimensions. The argumentation is rigorous: the speaker outlines the reduction to variance control, uses standard concentration inequalities (Hoeffding, Bernstein), and leverages algorithmic tools like multiplicative weights and regularized ERM. The logical flow is clear, and the claims are supported by technical sketches without falling into hand-waving. The presentation also situates the results within existing literature, highlighting gaps and connections.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is high: the talk is based on recent research, likely from top-tier venues, and the arguments are grounded in established theory (e.g., bandit lower bounds, VC/Natarajan dimensions). The speaker mentions collaborative works and acknowledges previous results, indicating a scholarly approach. The title accurately reflects the content; it precisely names the two problems addressed. No explicit external sources are cited in the description, but the talk itself references prior work. The presentation is self-contained enough for an expert audience, and the claims are clearly stated.
209 words
Title / Content Match
The title accurately reflects the content: the talk covers sample complexity bounds for sparse contextual bandits and multiclass classification, matching the title exactly.
Quality & Reliability
8/10
The talk presents rigorous theoretical results in machine learning, based on peer-reviewed research. The speaker is a researcher from Tel Aviv University, and the content is technically deep with formal proofs. The presentation is clear and the claims are backed by standard arguments. However, as a recorded lecture without full proof details, a slight deduction is made.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction to stochastic contextual bandits and the learning protocol.
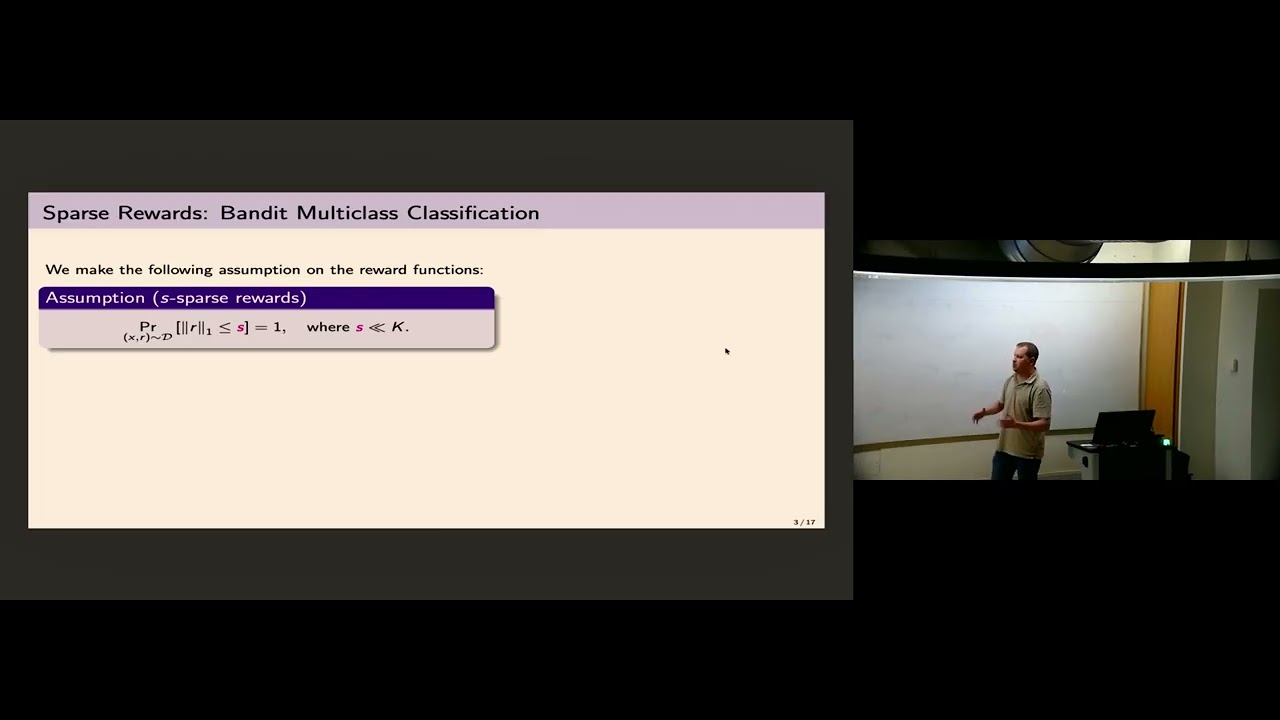
- Discussion of the sparsity assumption and the motivation for sparse rewards.
- Explanation of the algorithmic approach: low-variance estimation and multiplicative weight updates.
- Second part: multiclass classification, DS and Natarajan dimensions, and the tight sample complexity bound.
- Open questions and conclusion.
Contribution & Novelties
The talk presents a novel algorithm that closes a major gap in the sample complexity of sparse contextual bandits, achieving the optimal bound up to logarithmic factors. This is a significant advance as it removes the previous polynomial dependence on K. The second contribution provides the first tight bound on the agnostic PAC sample complexity for multiclass classification, revealing that both the DS dimension and the Natarajan dimension are necessary. This goes beyond existing characterizations. The use of a low-variance estimator and multiplicative weights is innovative and likely to inspire further work.
Pour aller plus loin :
- Contextual bandit — Provides background on the problem setting.
- Sample complexity — General definition and importance in learning theory.
- Multiplicative weight update method — The key algorithmic technique used.
- Natarajan dimension — The relevant dimension for multiclass learning.
135 words
Radar Profile
The radar profile shows very high scores in quantitative information, qualitative information, and technical level, indicating a dense and rigorous talk. The slightly lower reliability score (8) reflects that it is a recorded seminar rather than a peer-reviewed publication, but overall the profile is consistent with an excellent theoretical research presentation.