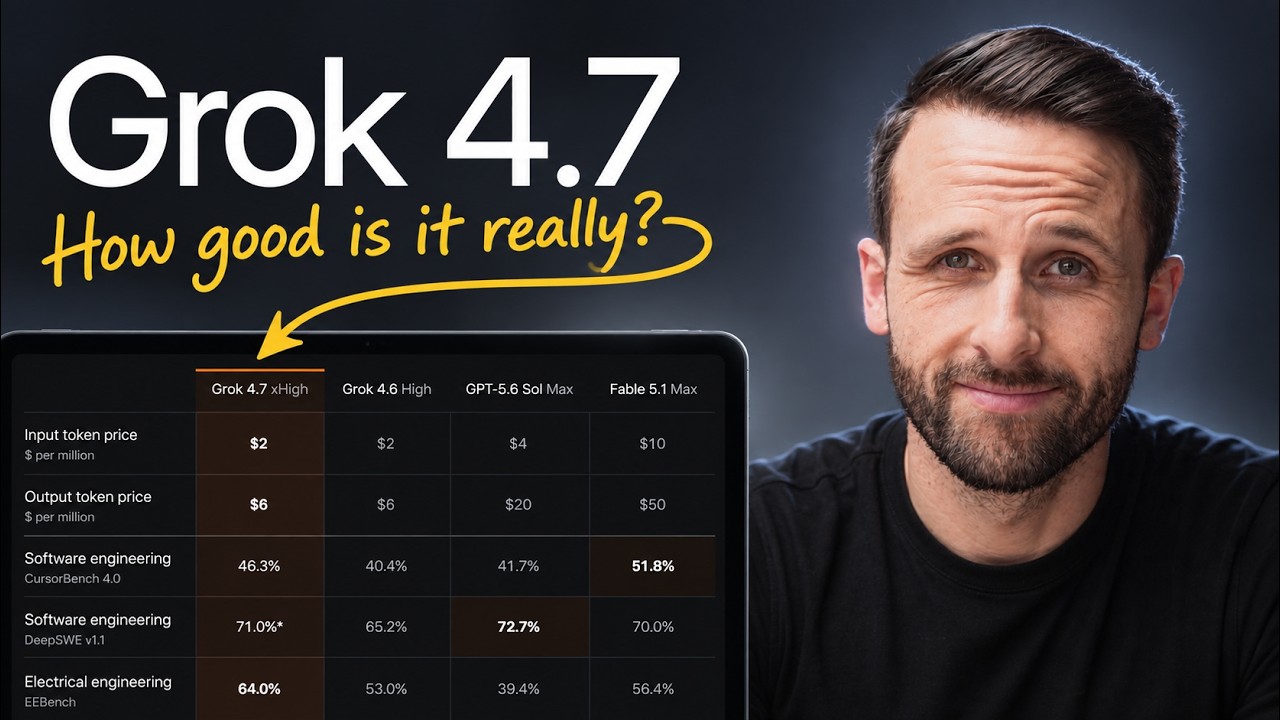
Grok 4.7: No-Hype Full Review & Testing
Keywords
Summary
160 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video offers practical value by directly testing models on realistic coding tasks rather than relying solely on benchmark scores. The custom tests include prompts that require creativity, visual accuracy, and functional implementation, providing a more holistic view of model capabilities. The argumentation is structured and transparent, with the creator openly acknowledging limitations such as one-shot attempts and the narrow scope of tests. He also discusses the potential bias in benchmarks since Cursor, used for one benchmark, is owned by xAI. The cost analysis adds practical insight for developers considering model adoption. However, the tests are subjective and limited to three scenarios, which may not generalize to all use cases, but the cautious conclusions are well-supported by the presented evidence.
Scientific Rigor, Source Quality, Title Accuracy
The review demonstrates reasonable rigor: the creator uses official benchmarks from xAI’s press release, clearly notes the missing GPT-6 Astra data, and conducts his own experiments with detailed prompts. He mentions that all prompts and results are available in his blog post, providing transparency. The title accurately reflects the content, and the description includes links for further exploration. The sources used are the creator’s own materials and the official press release, which is appropriately referenced. The analysis is fair in acknowledging both strengths and weaknesses of Grok 4.7, without overhype, aligning with the ’no-hype’ claim in the title.
233 words
Title / Content Match
The title accurately reflects the content, which is a practical, no-hype evaluation and testing of Grok 4.7 against other models.
Quality & Reliability
7/10
The review is based on transparent practical testing with clear methodology, including benchmark analysis, cost tracking, and token usage. The creator acknowledges limitations such as limited test count and potential bias in benchmarks (Cursor owned by xAI). The information is presented with appropriate caveats, making it reasonably reliable for an informal review.
Chapters
- Intro
- Benchmarks and Pricing
- Where Grok 4.7 Looks Competitive
- Test 1: Cloning an Awwwards Website
- Website Clone Results and Model Reveal
- Website Clone Costs and Build Times
- Test 2: Interactive 3D Keyboard Product Page
- 3D Website Results, Costs and Model Reveal
- Test 3: Building Mario Kart’s Rainbow Road
- Mario Kart Results, Costs and Model Reveal
- Final Verdict
Cited Sources
- AI for Mortals - Newsletter — Creator's newsletter for updates and related content.
- Grok 4.7 vs Fable 5.1 vs GPT-6 Astra - Live Links and Prompts — Blog post containing all prompts, live links, and detailed results for the tests.
Contribution & Novelties
This video provides a hands-on, realistic comparison of Grok 4.7 against leading models, focusing on practical coding tasks and cost efficiency. It goes beyond official benchmarks by testing creativity, design accuracy, and functional implementation, offering insights into real-world applicability. The cost and token analysis helps users understand the trade-offs between performance and expense.
Pour aller plus loin :
- Large language model — Provides background on LLMs and their capabilities, relevant to understanding the models tested.
- Benchmark (computing) — Explains how benchmarks are used to evaluate system performance, contextualizing the video’s benchmark analysis.
- Grok (chatbot) — Offers information on xAI’s Grok series, though may not cover version 4.7 specifically.
108 words
Radar Profile
The scores are relatively balanced, with quantity of information leading at 7, while quality, technical level, and reliability are each at 6. This suggests a moderately detailed and dependable review that is accessible but not deeply technical. The overall profile indicates a solid, practical evaluation with room for deeper analysis.