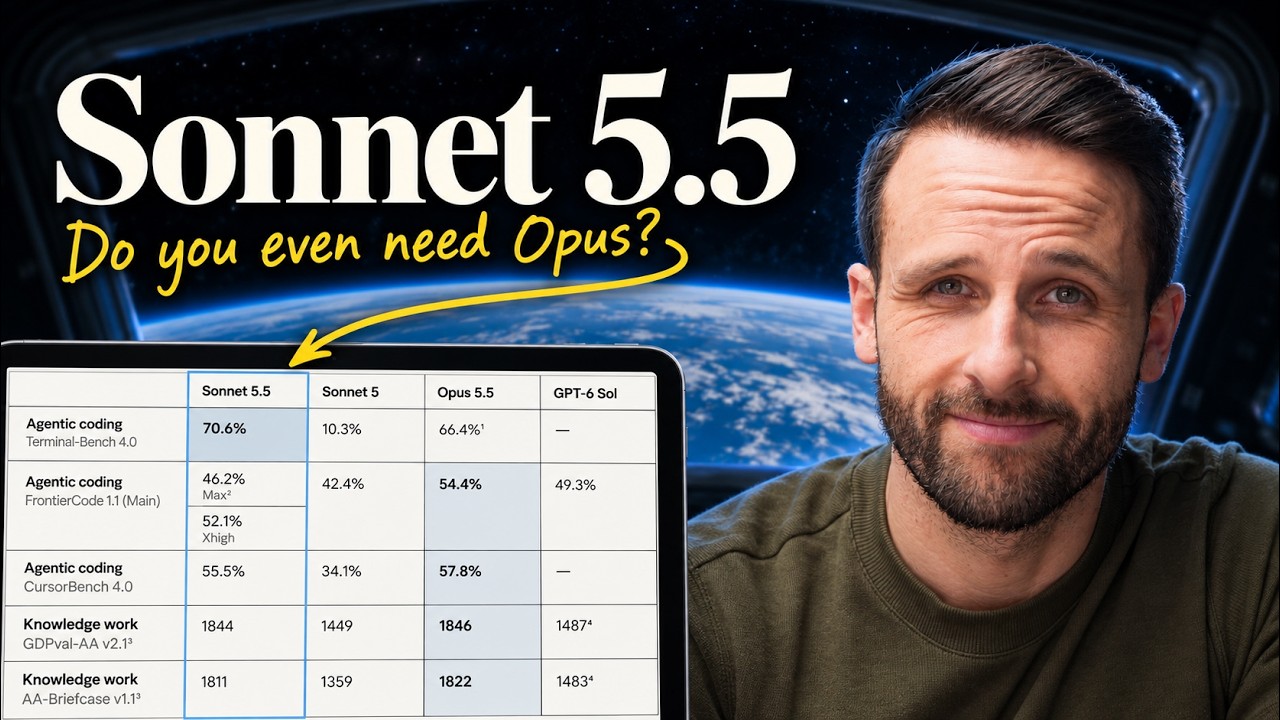
Sonnet 5.5: No-Hype Full Review & Testing
Keywords
Summary
188 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides substantial value by offering an independent, hands-on evaluation of Sonnet 5.5, backed by quantitative data on cost, tokens, and performance. The argumentation is solid: Simmons systematically compares benchmarks, runs identical prompts across models, and presents raw costs. He also nuances Anthropic’s claims by referencing third-party analysis about token usage at different effort levels. However, the testing is limited to three specific tasks, and the subjective quality rankings could be influenced by personal taste.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is decent; the methodology is reproducible to a degree, with prompts and skills provided in the blog post. Sources cited are Anthropic’s official data and his own experiments, plus a reference to Artificial Analysis. The title accurately reflects the content, promising a no-hype review and delivering detailed testing. The quality of sources is good, though all are from the creator’s own blog or company pages, lacking independent verification.
162 words
Title / Content Match
The title accurately reflects the content: a non-hyped, thorough review with hands-on testing and cost analysis.
Quality & Reliability
8/10
The review is systematic, comparing Sonnet 5.5 against several frontier models on benchmarks and real-world builds, with detailed cost and token tracking. However, the tests are limited to a few scenarios and the evaluation is subjective in parts.
Chapters
Cited Sources
- Sonnet 5.5 blog post with full prompts and builds — Detailed blog post containing prompts, live builds, and cost tables referenced in the video.
- AI for Mortals newsletter — Newsletter mentioned for further updates and content.
Contribution & Novelties
The video adds original value by conducting independent, real-world testing of Sonnet 5.5 against multiple frontier models, with a focus on cost efficiency and practical applications. It challenges Anthropic’s marketing claims by analyzing token usage at different effort levels, citing third-party measurements. The video also introduces a skill for creating launch videos, which is shared in the blog post.
Pour aller plus loin :
- Claude (language model) — Context on Anthropic’s Claude family and evolution.
- Large language model — Overview of LLMs, benchmarks, and evaluation methods.
- Terminal-Bench — Mentioned as a benchmark for AI agent capabilities; exact address uncertain.
99 words
Radar Profile
The radar chart likely shows high scores on information quantity and quality, with moderate technical depth and reliability, indicating a well-rounded but not flawless review.