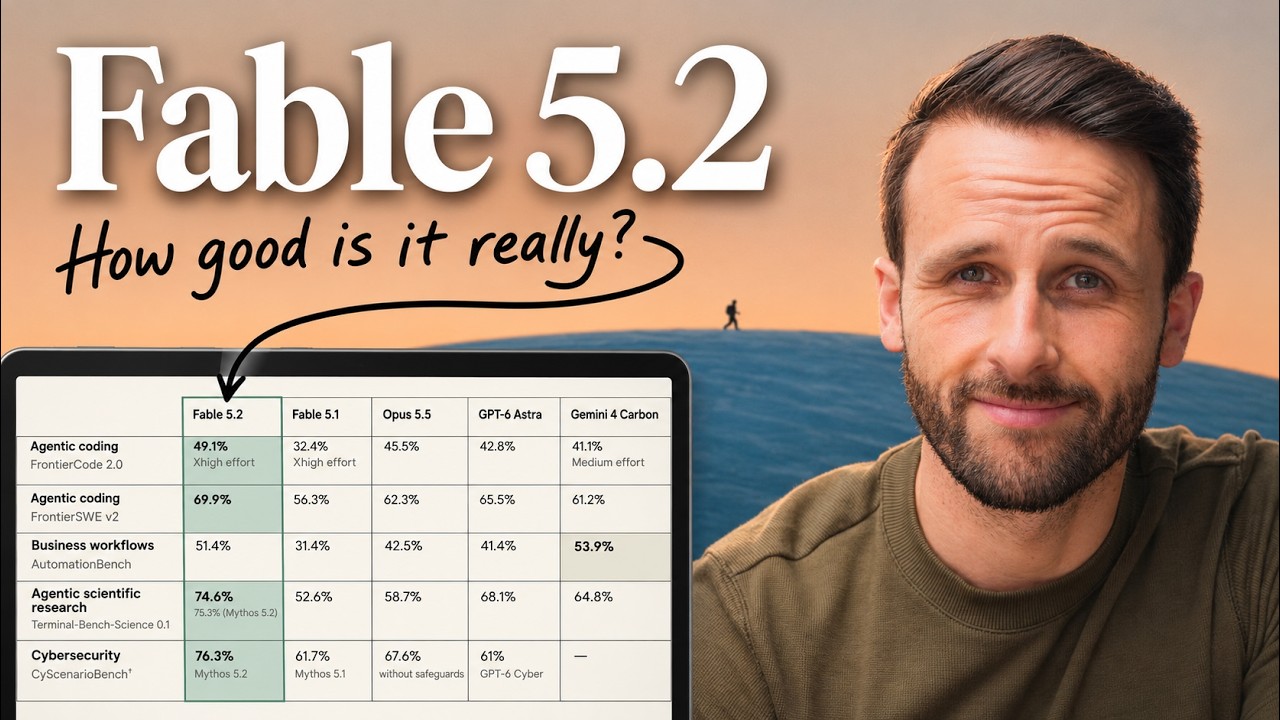
Fable 5.2: NO-HYPE Full Review (& Testing)
Title history
- Fable 5.2: NO-HYPE Full Review (& Testing) — observed on 20261110-0839 UTC (YouTube)
Keywords
Summary
174 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides substantial value by comparing models on realistic, complex tasks rather than simple benchmarks. The creator’s methodology is thorough, documenting time, tokens, and costs for each model on each task. The argumentation is solid: the creator acknowledges subjective aspects (e.g., visual quality) while grounding objective metrics in recorded data. The decision to test multiple models in parallel strengthens the comparison’s validity. However, the absence of statistical replication and reliance on single runs limit the conclusions, and the creator’s preferences (e.g., storytelling over bullet points) are subjective. Overall, the video offers practical insights for AI practitioners evaluating model performance.
Scientific Rigor, Source Quality, Title Accuracy
The video demonstrates scientific rigor by citing Anthropic’s official blog for benchmarks and pricing, and referencing specific test data available in the companion blog post. The creator transparently shares costs and timings, allowing viewers to replicate the methodology. The title accurately describes the content as a no-hype review with testing; it does not overpromise. The video does not mention external peer-reviewed sources but relies on primary data from Anthropic and hands-on experimentation. The only potential bias is the sponsor segment, which is clearly disclosed and does not affect the model evaluations.
206 words
Title / Content Match
The title accurately reflects the content: a no-nonsense full review with hands-on testing across multiple scenarios.
Quality & Reliability
7/10
The video provides a systematic comparison of multiple AI models on three complex build tasks, with detailed cost and time metrics. The creator's methodology is transparent and benchmarks are referenced from Anthropic's official blog, but the evaluation relies on subjective assessment of outputs and does not include independent verification.
Chapters
Cited Sources
- Fable 5.2 blog post - Full builds, prompts, and costs — Contains detailed information about the test builds, prompts, and cost receipts mentioned in the video.
External References
Contribution & Novelties
This video offers a hands-on, comparative evaluation of Fable 5.2 against competing frontier models on complex, real-world tasks, providing practical insights into performance, cost, and speed. The creator’s approach of timing and costing each build adds a useful economic dimension often missing from official benchmarks.
Pour aller plus loin :
- Large language model — Background on the technology behind Fable 5.2.
- AI benchmark — Overview of standardized tests used to evaluate AI models.
- Multi-agent system — Related to the orchestrator and sub-agent usage discussed in the video.
- Claude (Anthropic) — Official page for Anthropic’s model family, including Fable.
98 words
Radar Profile
The radar profile shows high scores in information quantity and technical depth, moderate quality and reliability, and somewhat lower global reliability due to subjective evaluation. This suggests a technically rich but not fully objective review.