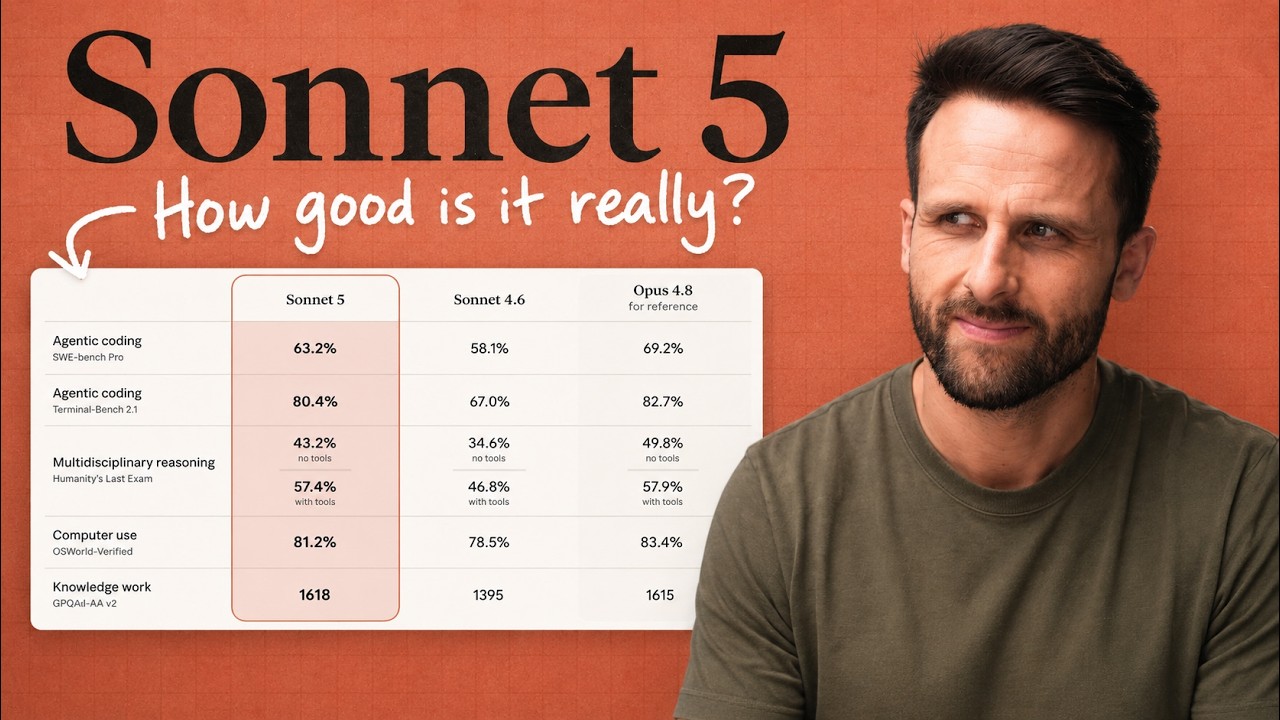
Claude Sonnet 5: No Hype Full Breakdown & Testing
Keywords
Summary
171 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides significant value through hands-on, practical testing that goes beyond abstract benchmarks. The argumentation is data-driven, with clear cost comparisons, token usage, and time-stamped results. The creator acknowledges subjectivity in design and writing tests, and notes limitations in the one-shot nature of the assessments. The use of a blind study reduces bias, and the inclusion of failure cases (e.g., broken outputs) adds credibility. However, the lack of rigorous statistical analysis and the small number of tests per category limit the generalizability of conclusions.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is moderate. The creator references known benchmarks (Pro & Terminal Bench, Humanity’s Last Exam) but does not provide direct links or in-depth methodological details. The SimmonsBench suite is self-created and not externally validated. The video does include detailed prompts and outputs, allowing viewers to assess results independently. The title matches the content well, accurately promising a breakdown and testing without hype. The only external links provided are for the creator’s bootcamp and newsletter, which are not scientific sources but rather promotional content; thus, the sourcing is weak for verifying specific claims.
194 words
Title / Content Match
The title accurately reflects the content: the video provides a comprehensive, no-hype breakdown and hands-on testing of Claude Sonnet 5 against previous models.
Quality & Reliability
7/10
The creator runs a structured benchmark suite (SimmonsBench) with blind grading, provides detailed examples, and includes cost comparisons. However, the methodology is not peer-reviewed, some tests are subjective (design/writing), and the sample size is limited (15 coding builds, 4 knowledge tasks).
Chapters
- Intro
- Firing up SimmonsBench (15 builds, 3 models)
- The benchmarks: where Sonnet 5 lands
- Coding test 1: Designer portfolio site
- Coding test 2: Excalidraw clone
- Coding test 3: 3D nebula galaxy
- Coding test 4: Racing game
- Coding test 5: Low-poly terrain flyover
- Coding verdict: Opus takes it
- Knowledge work tests begin
- Knowledge test 1: Sales QBR deck
- Knowledge test 2: Finishing my essay
- Knowledge test 3: LinkedIn post
- Knowledge test 4: Writing a YouTube hook
- Final verdict + takeaways
Cited Sources
- AI Bootcamp (persimmons.studio) — Mentioned in description as a paid course, not a scientific source.
- AI for Mortals Newsletter — Subscription link in description, not related to benchmarks.
Contribution & Novelties
The video contributes a practical, user-centric evaluation of Claude Sonnet 5, highlighting real-world performance and cost efficiency. It introduces SimmonsBench as a benchmarking approach, though details are not fully disclosed. The comparison across coding and knowledge work is novel in scope, combining quantitative benchmarks with qualitative assessments.
Pour aller plus loin :
- Large language model — Overview of LLMs, relevant for understanding the context of Sonnet 5.
- Benchmark (computing) — General concept of benchmarks used in AI evaluation.
- Humanity’s Last Exam — Reference to the reasoning benchmark mentioned in the video, if applicable.
93 words
Radar Profile
The profile shows high information quantity (9) and good quality (8), with moderate technical depth (7) and reliability (7). This indicates a content-rich, practical evaluation that is well-illustrated but lacks formal scientific rigor, fitting a balanced but not fully academic review.