NLP: Self-supervised Models (or: "How to grow language models") - Lecture 1 - Fall 2026
Keywords
Summary
162 words
Critical Evaluation
Value of the Information & Strength of the Argument
The lecture provides a solid conceptual foundation for understanding self-supervised learning. The instructor’s argumentation is clear and well-structured, using concrete examples to illustrate abstract concepts. He effectively motivates the importance of the topic by highlighting both the remarkable capabilities and the limitations of current models. The historical narrative is engaging and helps contextualize the field’s evolution. The discussion of terminology is particularly valuable for students, as it clarifies commonly confused terms. The argumentation is persuasive, though it relies on anecdotal evidence for some claims (e.g., the Jacobian conjecture example) rather than rigorous citations.
Scientific Rigor, Source Quality, Title Accuracy
The lecture demonstrates scientific rigor in its conceptual explanations and historical account. The instructor, a faculty member at JHU, provides a coherent framework for the course. However, the lecture does not cite specific research papers or sources for the claims made, relying instead on general knowledge and anecdotal examples. The course website is mentioned as a resource, but no direct references are provided. The title accurately reflects the content, which focuses on self-supervised models and their role in language model development. The lecture is well-organized and the content aligns with the title.
200 words
Title / Content Match
The title accurately reflects the lecture's focus on self-supervised models and their role in language model development.
Quality & Reliability
8/10
Lecture by a recognized academic (JHU) providing a coherent conceptual framework for self-supervised learning, with historical context and clear definitions. The content is pedagogical and generally accurate, though it includes anecdotal examples (e.g., Jacobian conjecture) that are not formally verified.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction and course overview
- Motivating example: Jacobian conjecture and LLM
- Discussion of LLM capabilities and limitations
- Definition of self-supervised models
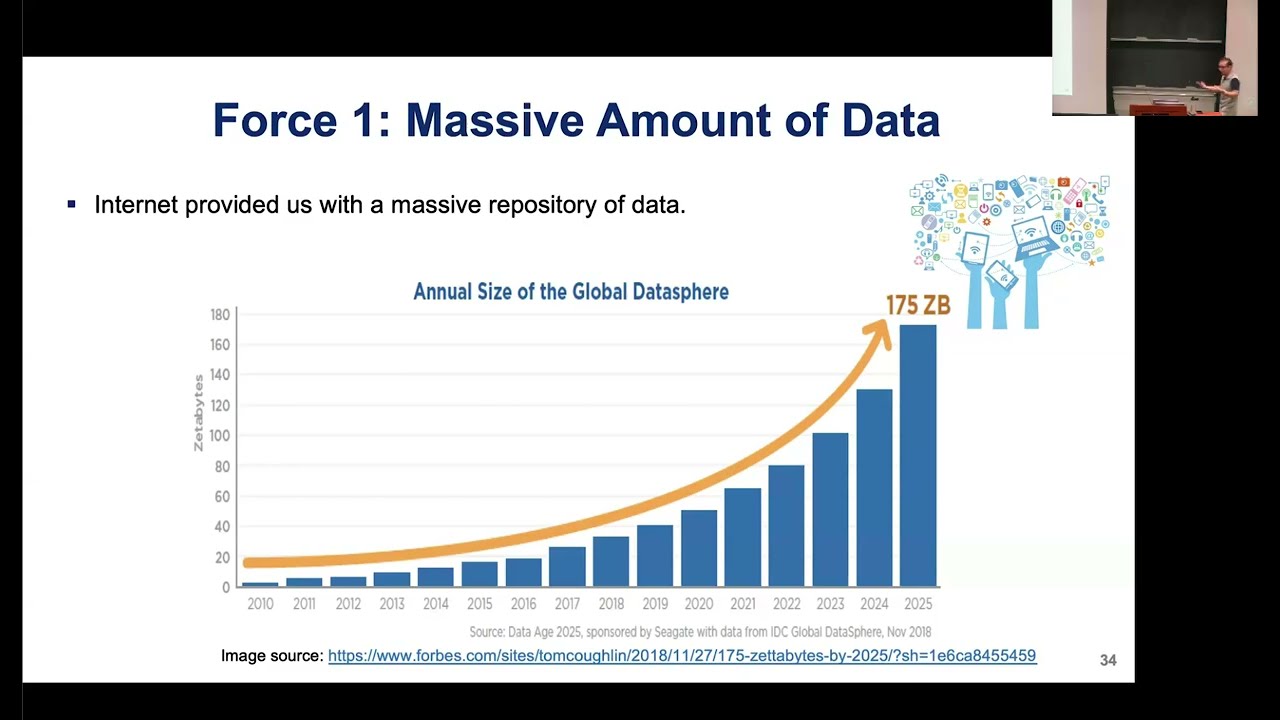
- History of neural networks and key forces
- Terminology: pre-trained, generative, foundation, frontier models
- Course objectives and topics
- Logistics and grading policy
Cited Sources
- Course website: Self-Supervised Models (Fall 2026) — Mentioned as the primary resource for course materials, schedule, and reading list.
Concurring Sources
- Course website — The course website is the official source for the lecture content and aligns with the topics discussed.
Contribution & Novelties
The lecture provides a comprehensive introductory framework for self-supervised learning, emphasizing the conceptual definition and historical context. It offers a clear taxonomy of related terms (pre-trained, generative, foundation, frontier models), which is valuable for students entering the field. The lecture also highlights the importance of both technical and soft skills for careers in AI.
Pour aller plus loin :
- Self-supervised learning — Wikipedia overview of the paradigm.
- Transformer (machine learning) — Key architecture discussed in the course.
- McCulloch–Pitts neuron — Historical foundation of neural networks.
- Scaling law (neural networks) — Relevant to the discussion of model scaling.
97 words
Radar Profile
The radar profile shows high scores in quality of information and reliability, reflecting the academic rigor of the lecture. The quantity of information is moderate, as it is an introductory lecture. The technical level is intermediate, suitable for graduate students but not highly advanced. Overall, the lecture is well-balanced and provides a solid foundation.